05 / 06
Cloud and infrastructure
Deployment, hosting and delivery pipelines sized to the problem, so releases are routine and problems surface before users find them.
WHAT IT IS
Infrastructure that stays out of the way.
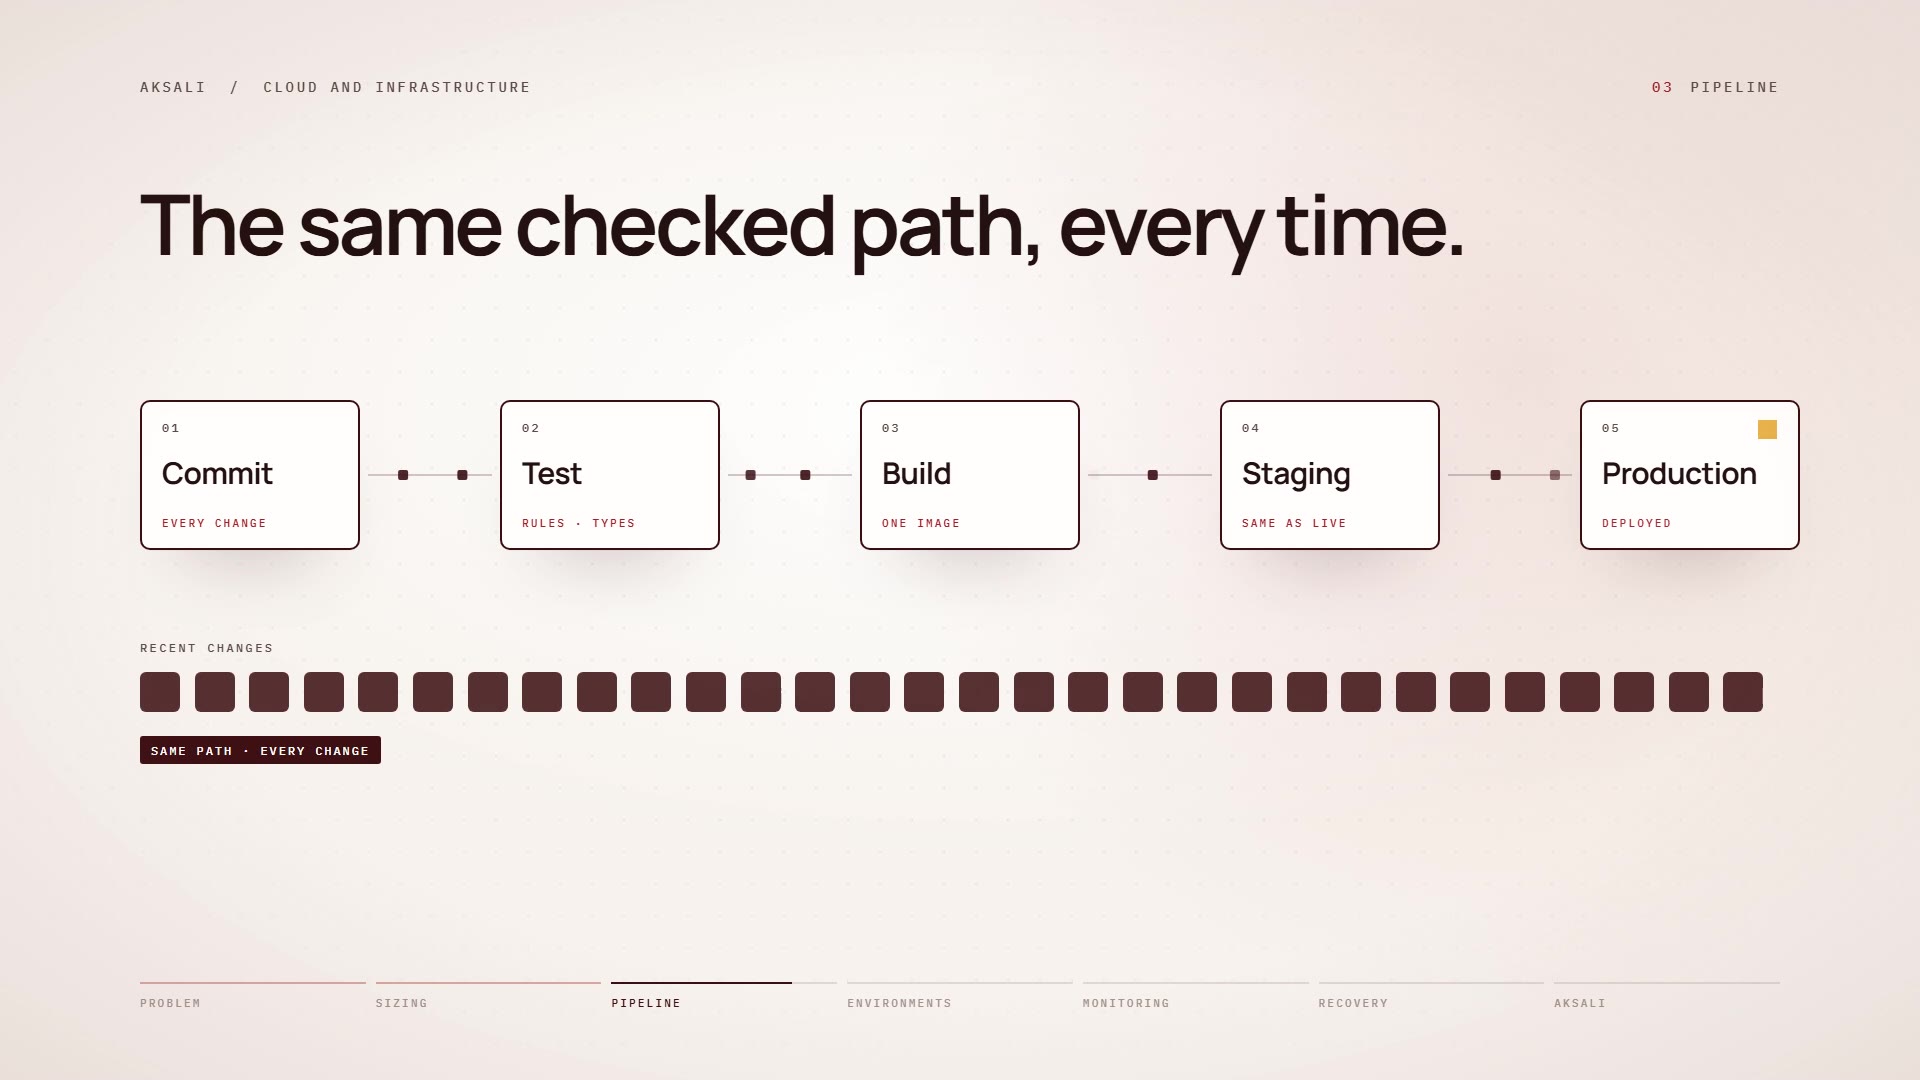
Good infrastructure is mostly invisible. Code moves from a commit to production along the same checked path every time, environments match, secrets stay secret, and when something breaks, someone knows before a user does.
We build that, and we keep it as simple as the problem allows: a managed platform where it fits, containers and more control where it does not.
PROBLEMS WE SOLVE
What usually makes releases hard
Infrastructure problems tend to show up as fear: of deploying, of changing, of the next outage.
- 01
Releases that feel risky
Manual deployments and release-day nerves. We automate the path to production so that releasing becomes routine.
- 02
Environments that drift apart
It works on one machine and not another. We make development, preview and production reproducible.
- 03
Complexity out of proportion
Infrastructure designed for a scale that does not exist yet. We size it to what the product needs today.
- 04
Outages discovered by users
No monitoring and no alerts. We add health checks and alerting, so problems reach you first.
HOW WE WORK
From a commit to production, the same way every time
Choose the simplest platform that fits, then make every release automatic, safe and observable.
Size it to the problem
We look at the workload, the traffic and the risks, and choose the simplest platform that fits.
Automate the path
Every change is built, tested and deployed by a pipeline, with a preview before it reaches production.
Keep secrets secret
Credentials live in managed stores, access is least-privilege, and configuration is validated at start-up.
Know before users do
Health checks, logs and alerts make failures visible, explainable and recoverable.
FILM0:50
Cloud and infrastructure at Aksali, in one minute
From sizing to a checked delivery path, identical environments, monitoring and one-step recovery.
Read the transcript
For many teams, every release feels like a risk. The better question is how to make releases routine.
We size the infrastructure to the problem, not to the trend. Built for the load you have, with a clear path to grow.
Every change takes the same checked path: test, build and deploy.
Environments stay identical, and secrets stay in managed stores.
Monitoring tells you about a problem before your users do.
And if a release goes wrong, rolling back is a single step.
Infrastructure that is automated, observable and routine. Aksali Technologies. Genuine engineering.
WHAT WE PROVIDE
What we provide
Cloud deployment
Hosting on managed platforms or cloud providers, matched to the workload and the budget.
CI/CD pipelines
Automated build, test and deploy, with a preview environment for every change.
Containerisation
Docker images that make environments reproducible from a laptop to production.
Configuration and secrets
Settings and credentials handled safely, and checked when the application starts.
Monitoring and alerting
Health checks, logs and alerts that find problems before users do.
Infrastructure review
An assessment of an existing setup for cost, reliability and security, with prioritised fixes.
TYPICAL APPLICATIONS
Typical engagements
- 01
Get a product into production properly
Hosting, pipeline, secrets and monitoring set up together, documented and handed over.
- 02
Make releases routine
A manual, nervous release process replaced by an automated, checked one.
- 03
Review an existing setup
An honest assessment of what you run today, and what to change first.
WHY IT IS DIFFERENT
Sized to the problem, not the trend
The best infrastructure is the least you need, operated well.
| Common practice | How we work |
|---|---|
| Build for an imagined scale | Build for the load you have, with a clear path to grow |
| Deploy by hand, carefully | Deploy automatically, the same checked way every time |
| Keep secrets in configuration files | Keep secrets in managed stores, validated at start-up |
| Find out from users | Find out from monitoring |
WHAT TO EXPECT
What you can expect
A direct line to the engineer
You speak with the person designing and building your system, from the first call to hand-over.
A written plan before we build
What we will build, how, what it will take, and how we will know it works.
Working software early
Short increments you can see and test, rather than one reveal at the end.
Honest reporting
Results reported with their limits, and a clear word when a simpler approach would serve you better.
Everything handed over
Code, documentation and what you need to run and extend the system yourselves.
Want releases to feel routine?
Tell us how you deploy today and what worries you. We will suggest the smallest change that makes the biggest difference.
Start a conversation